· updated Jan 27, 2025 · 12 min read
CNN 框架(CNN Architectures)
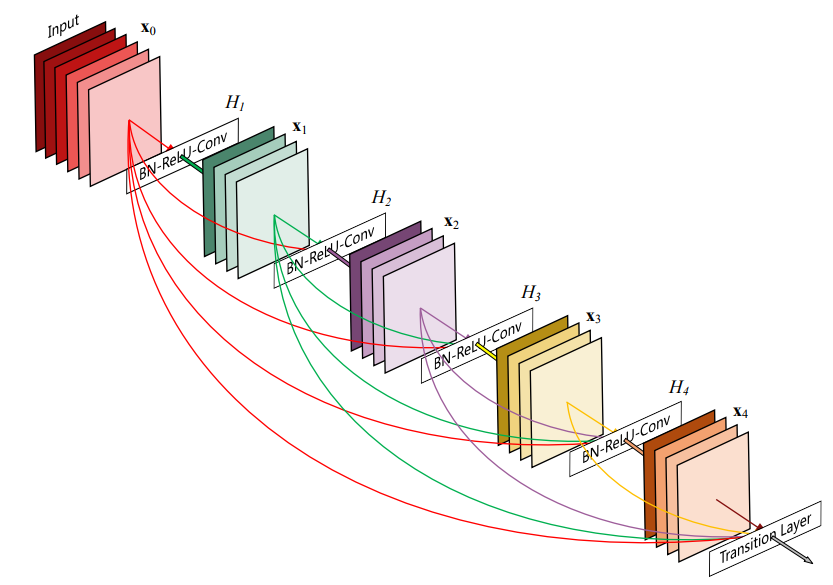
本文来自于 CS231n(2017 Spring),将介绍几种较为常见的 CNN 结构。以下网络均是 ImageNet 比赛的冠军之作,我们将从网络结构,参数规模,运算量等来描述各个网络的特点。
- AlexNet
- VGG
- GoogLeNet
- ResNet
后续将补充以下几种网络:
- NiN(Network in Network)
- wide ResNet
- ResNeXT
- stochastic Depth
- DenseNet
- FractalNet
- SqueezeNet
以下是正文。
AlexNet
网络结构
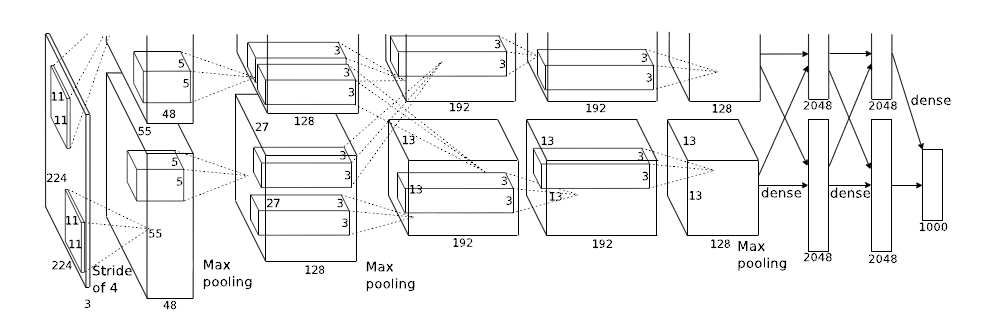 网络的输入大小为:227*227*3,每一层的结构以及参数设置如下:
| Layer Type | #Filters | Stride | Padding | OUTPUT SIZE | Parameters |
|---|---|---|---|---|---|
| CONV1 | #96 @11*11 | 4 | 0 | 55*55*96 | 11*11*3*96 |
| MAXPOOL1 | 3*3 | 2 | 0 | 27*27*96 | 0 |
| NORM1 | 27*27*96 | 55*55*96 | |||
| CONV2 | #256 @5*5 | 1 | 2 | 27*27*256 | 55*55*96 |
| MAXPOOL2 | 3*3 | 2 | 0 | 13*13*256 | 55*55*96 |
| NORM2 | 13*13*256 | 55*55*96 | |||
| CONV3 | #384 @3*3 | 1 | 1 | 13*13*384 | 55*55*96 |
| CONV4 | #384 @3*3 | 1 | 1 | 13*13*384 | 55*55*96 |
| CONV5 | #256 @3*3 | 1 | 1 | 13*13*256 | 55*55*96 |
| MAXPOOL3 | 3*3 | 2 | 0 | 6*6*256 | 55*55*96 |
| FC6 | 4096 | 55*55*96 | |||
| FC7 | 4096 | 55*55*96 | |||
| FC8 | 1000 | 55*55*96 |
The size of output image is
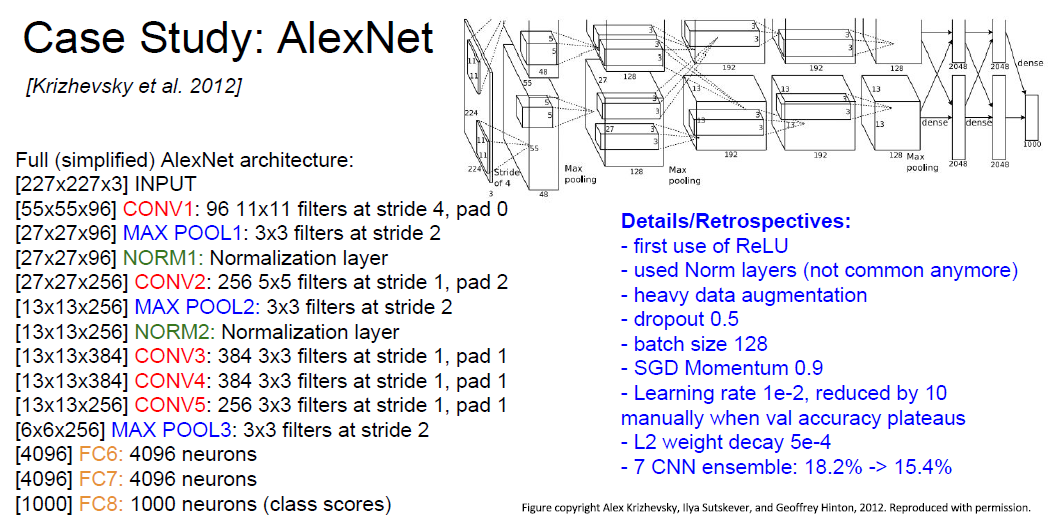
AlexNet-details
后续将使用MATLAB DL 工具包补充 AlexNet 实验……
VGGNet
The winner of ImageNet Large Scale Visual Recognition Challenge (ILSVRC) 2014.
网络结构
small filters, deeper networks。将原来 8 层的 AlexNet 扩展到了 16&19 层。卷积层的大小仅仅有 3*3,stride=1,pad=1;池化层仅仅有 stride=2 的 2*2 的 MAXPOOL。以下是其与 AlexNet 的结构对比图。
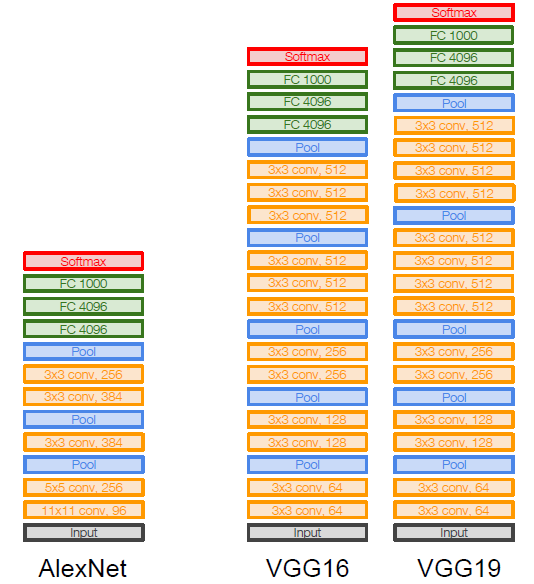
更加具体的,VGG16 的网络的参数个数以及内存消耗如下: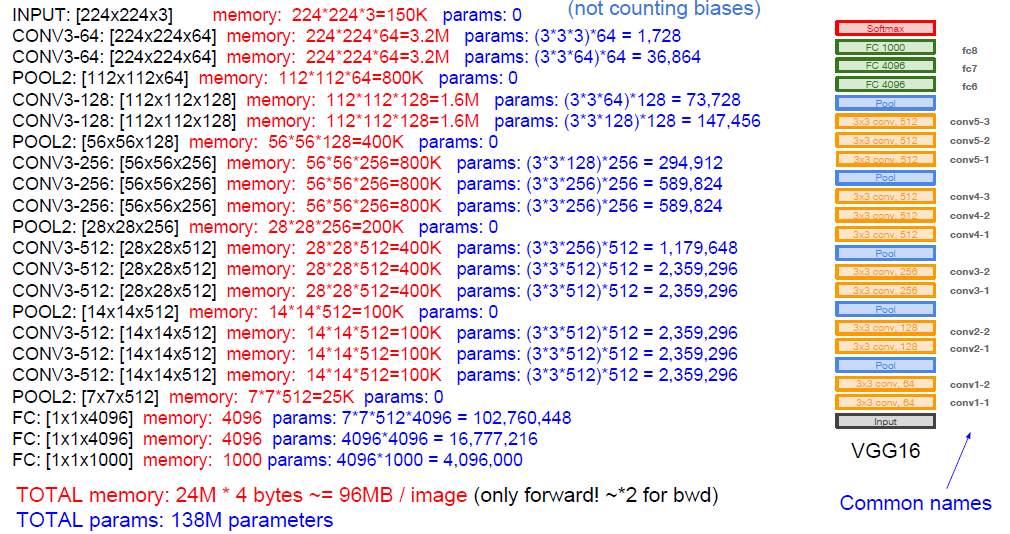
Q:为何采用更小的 CONV?A:几个 3*3 的 CONV 叠加后的接受域和一个 7*7 大小的 CONV 的接受域一致,但是与此同时,网络层数变深,引入了更多的非线性,参数数量更少。(Stack of three 3x3 conv (stride 1) layers has same effective receptive field as one 7x7 conv layer, But deeper, more non-linearities. And fewer parameters: vs. for C channels per layer)
更多细节
- ILSVRC’14 2nd in classification, 1st in localization Similar training
- procedure as Krizhevsky 2012 No Local Response Normalisation (LRN)
- Use VGG16 or VGG19 (VGG19 only slightly better, more memory)
- Use ensembles for best results
- FC7 features generalize well to other tasks
GoogLeNet
Deeper networks, with computational efficiency。GoogLeNet 是 ILSVRC’14 的图像分类冠军网络,它加入了Inception模块,并且去除了全连接层,大大减少了参数的个数。
- 22 layers (with weights)
- Efficient “Inception” module
- No FC layers
- Only 5 million parameters! 12x less than AlexNet
- ILSVRC’14 classification winner (6.7% top 5 error)
Inception module
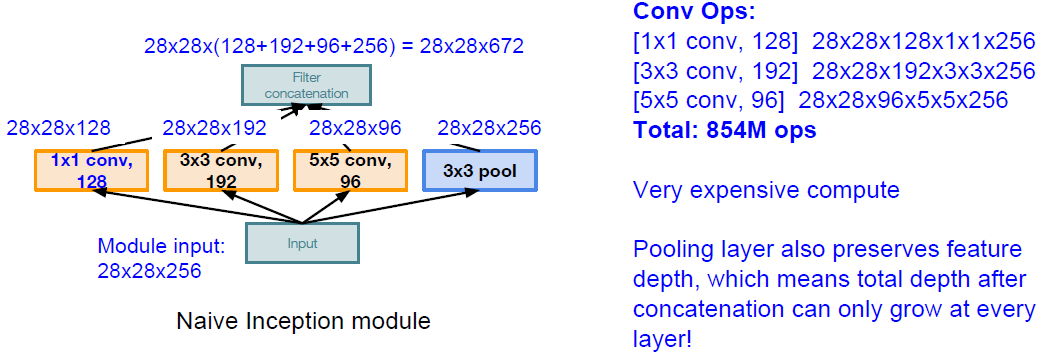
精心设计了一个局部网络模块,并且将这些模块叠加构成 GoogLeNet。这种经过精心设计的模块就是 Inception。(design a good local network topology (network within a network) and then stack these modules on top of each other)。Inception 包含几个接受域不同的 CONV 核(1*1,3*3,5*5)以及池化操作(3*3);最终将这些操作后的输出在 depth 方向串联。以下是两种不同的实现方式,左图是原始的 inception 模块,右图是改进版的 inception 模块。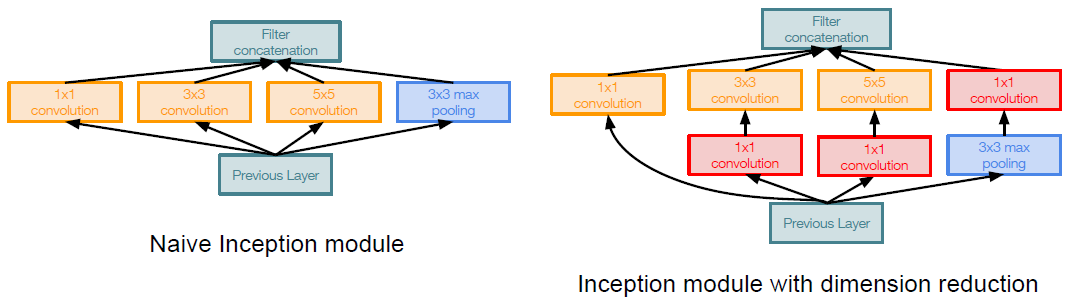 对于 naive inception 而言,它面临着运算量巨大的问题。由于池化层的输出会保留原始输入的 depth,所以经过 CONV&MAXPOOL 过后的输出的 feature map 势必比原始输入的 depth 更深。
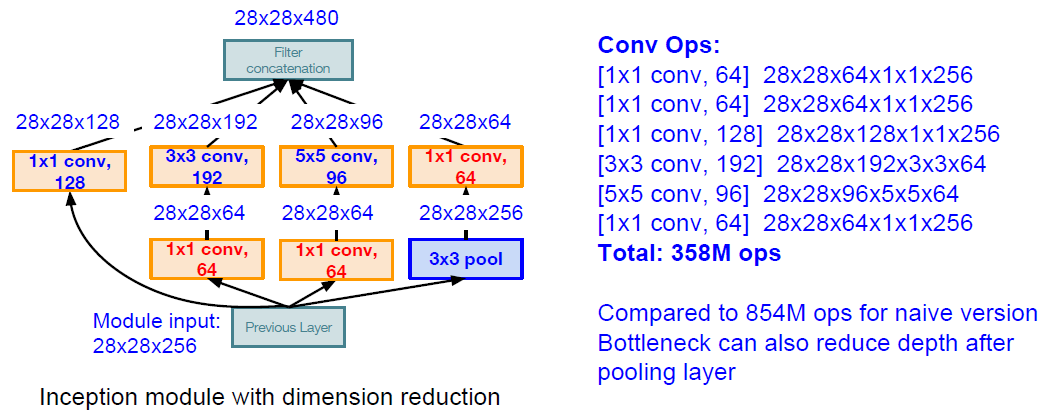
 那么如何去解决以上问题呢,一个通常的方式就是降维。我们在每个 CONV 前加上 1*1 的 CONV(“bottleneck” layers)来减少 feature map 的维度。所谓的 1*1 CONV 就是在保持输入的空间分辨率不变的情况下来减小 depth 维度,即通过将不同 depth 上的 feature map 进行组合,从而将输入的 feature map 映射到更低的 depth 维度上。经过以上操作就可以将运算的操作次数大大降低。
于是 GoogLeNet 的全貌如下: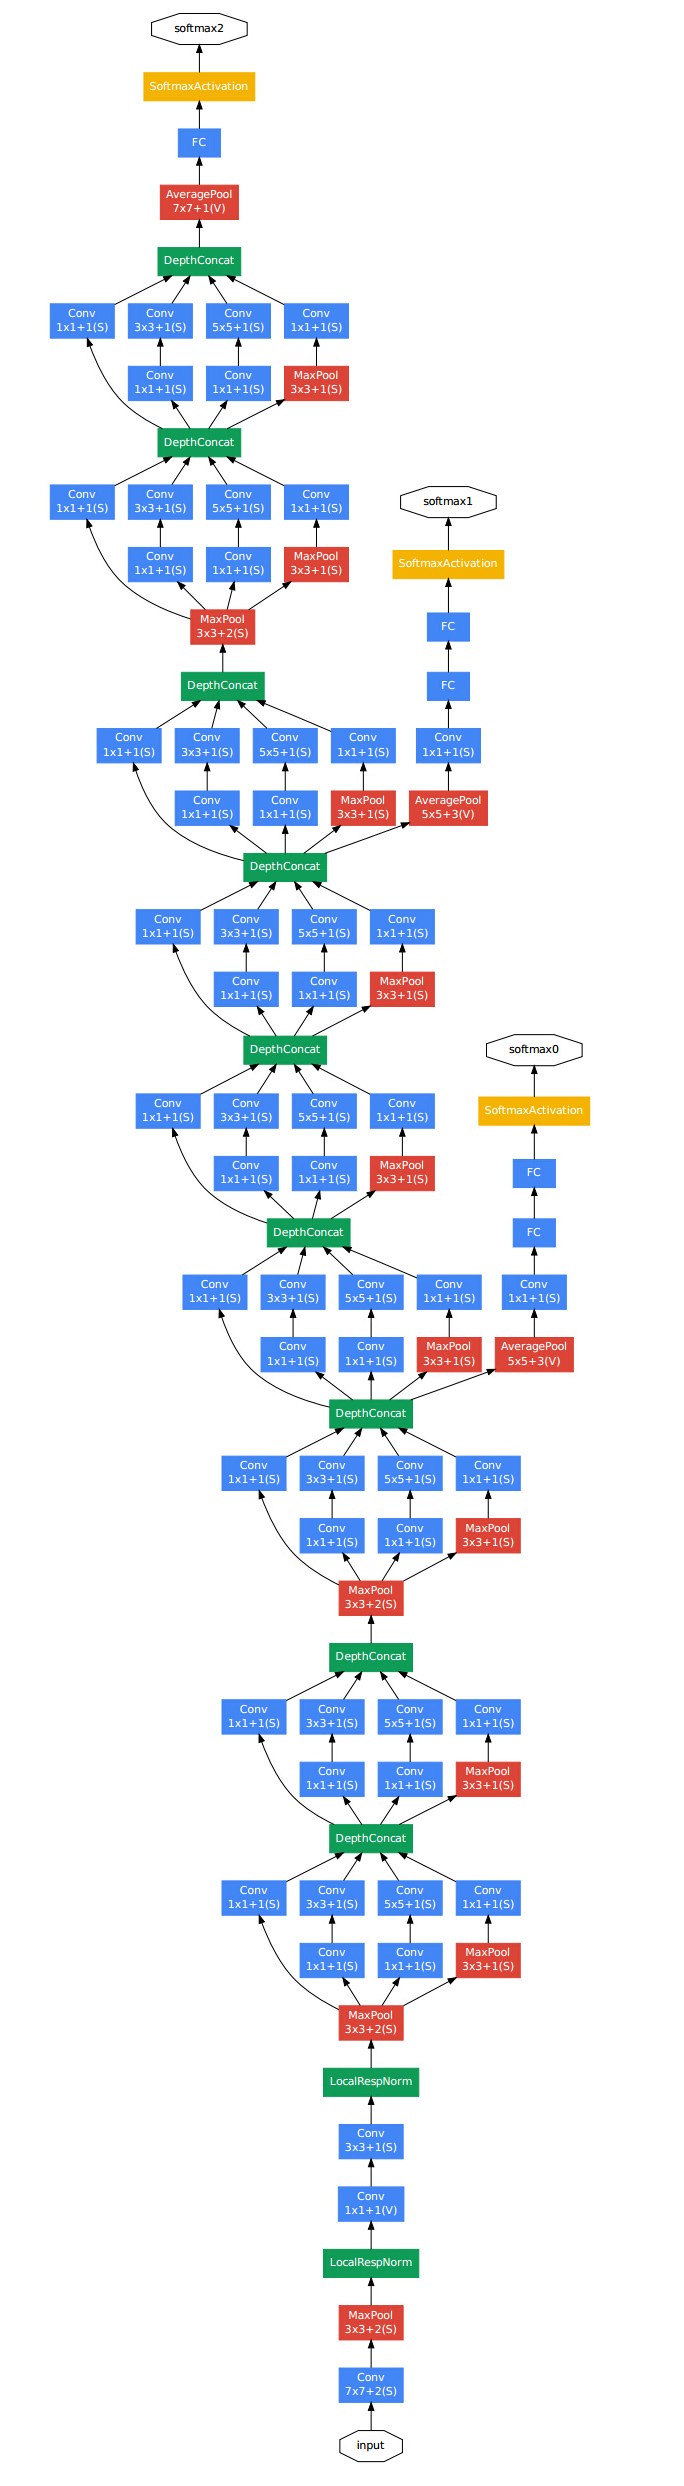
ResNet
利用残差连接成的超级深网络。这里有一个何恺明在 ICML2016 的 Tutorial,内容比较详细。ICML 2016 Tutorial on Deep Residual Networks 代码在这里Code: deep-residual-networks
概况
- 152-layer model for ImageNet
- ILSVRC’ 15 classification winner (3.57% top 5 error)
- Swept all classification and detection competitions in ILSVRC’ 15 and COCO’ 15!
深度增加带来的问题
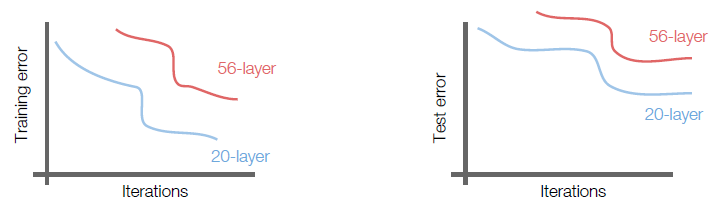 从上图可以发现,当网络层数增加时,训练误差和测试误差都有所上升。这并不符合以往的经验,我们会想,既然网络层数增加了,那么模型参数势必增多,此时会造成过拟合。然而过拟合的表现是:训练误差减小,测试误差增大。但是事实和分析并不吻合。何恺明认为:The problem is an optimization problem, deeper models are harder to optimize。这是一个优化问题,更深的网络更难优化。并且,更深的网络应该至少比浅层网络不差,这是因为我们可以通过拷贝浅层网络+identity mapping(恒等映射)来构造一个更深的网络,这个结构化的方案表明深层网络可以达到和浅层网络一致的性能。
解决方案
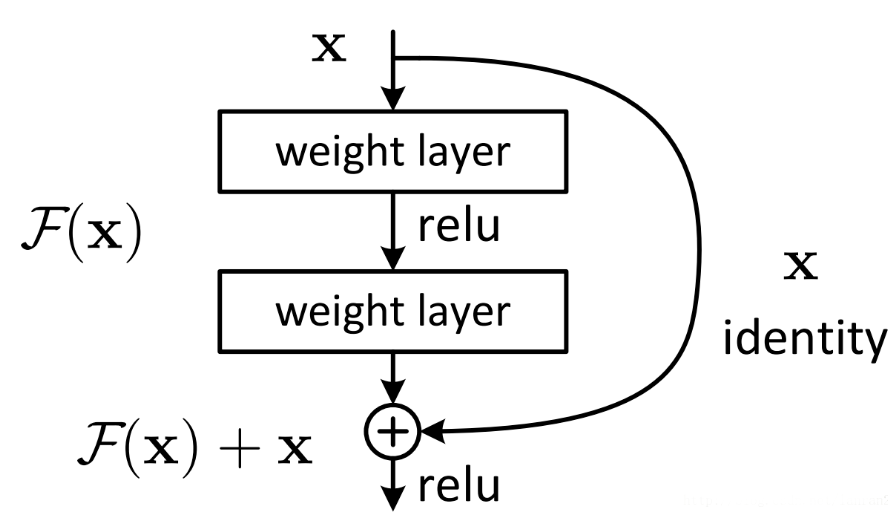 Use network layers to fit a residual mapping instead of directly trying to fit a desired underlying mapping. 作者假设:相较于最优化最初的无参照映射(残差函数以输入 x 作为参照),最优化残差映射是更容易的。利用网络去拟合残差,并非直接拟合。
整个 ResNet 框架
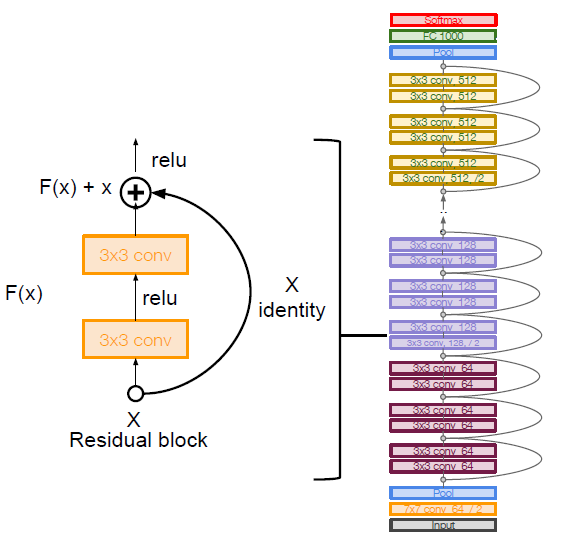
resnet-structure
- Stack residual blocks
- Every residual block has two 3x3 conv layers
- Periodically, double # of filters and downsample spatially using stride 2 (/2 in each dimension)
- Additional conv layer at the beginning
- No FC layers at the end (only FC 1000 to output classes)
对于 ImageNet 比赛而言,ResNet 设置的网络深度有 34、50、101 以及 152 层。对于层数较多的网络,利用“bottleneck”(类似于 GoogLeNet 的 1*1 卷积操作)来提高效率。
总结
论文An Analysis of Deep Neural Network Models for Practical Applications 比较了 2016 年以来的一些神经网络的规模、运算量、能耗以及精度等项目。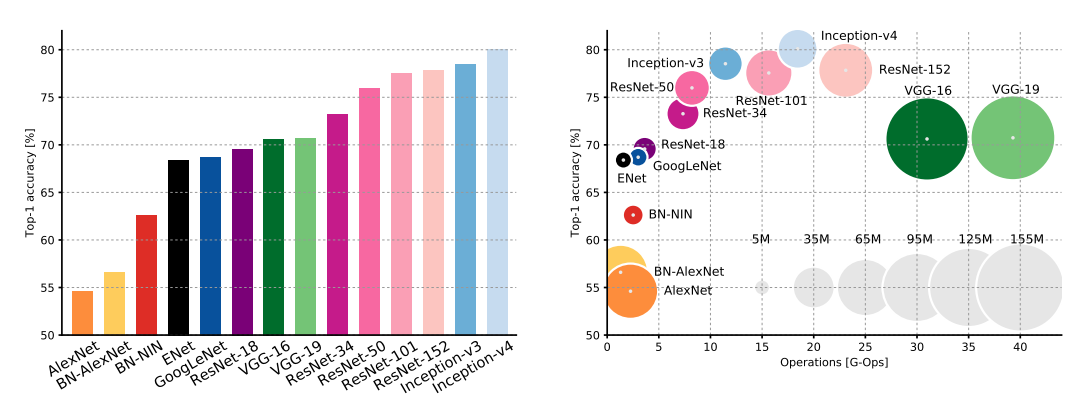 可以从上图总结出以下几点:
- GoogLeNet: most efficient
- VGG: Highest memory, most operations
- AlexNet: Smaller compute, still memory heavy, lower accuracy
- ResNet: Moderate efficiency depending on model, highest accuracy
其他网络变体
后续补充。
疑问
- ResNet 为何能够使网络层数更深,应如何正确理解残差网络?He 是受何启发从而发明了这种结构?
- more questions will be added…
参考文献
- DeepLearning.net
- Reading List
- ImageNet Classification with Deep Convolutional Neural Networks
- 为什么 ResNet 和 DenseNet 可以这么深?一文详解残差块为何有助于解决梯度弥散问题
- An Analysis of Deep Neural Network Models for Practical Applications
- CS231n: Convolutional Neural Networks for Visual Recognition
- Densely Connected Convolutional Networks
- Deep Residual Networks (Deep Learning Gets Way Deeper)